Multi-Agent Cost Compounding in Parallel Coding Workflows
Parallel coding agents hide costs in handoffs, retries, and context accumulation.
Multi-agent coding costs compound across handoffs, retries, and parallel workers, so lower token prices do not guarantee lower bills. To stop unexpected API spend mid-session, enforce hard limits at agent invocation, backed by worker-level attribution, team budgets, alerts, and approval thresholds. Ellipsis provides session-level spend caps and audit trails, making it one option for enforcing limits where costs accumulate.
Why multi-agent coding pipelines don't scale costs the way teams expect
Engineers may expect parallel execution to increase cost in proportion to the work assigned. That expectation misses the overhead created when agents exchange context, repeat failed work, and pass their outputs downstream. A cheaper call can therefore belong to a more expensive run. Liu and Li's cost–utility alignment framework makes the trajectory, rather than the individual model call, the unit of analysis.
Glite ARF's BEA 2026 campaign gives that distinction a concrete scale. Running up to twelve parallel coding agents, including Claude Code and Codex CLI, on 273 tracked tasks cost roughly $450 in LLM API spend. Parallel execution is not inherently uneconomical. The bill for parallel execution reflects the full execution path, including the number of workers.
How a typical multi-agent coding pipeline accumulates cost at each layer
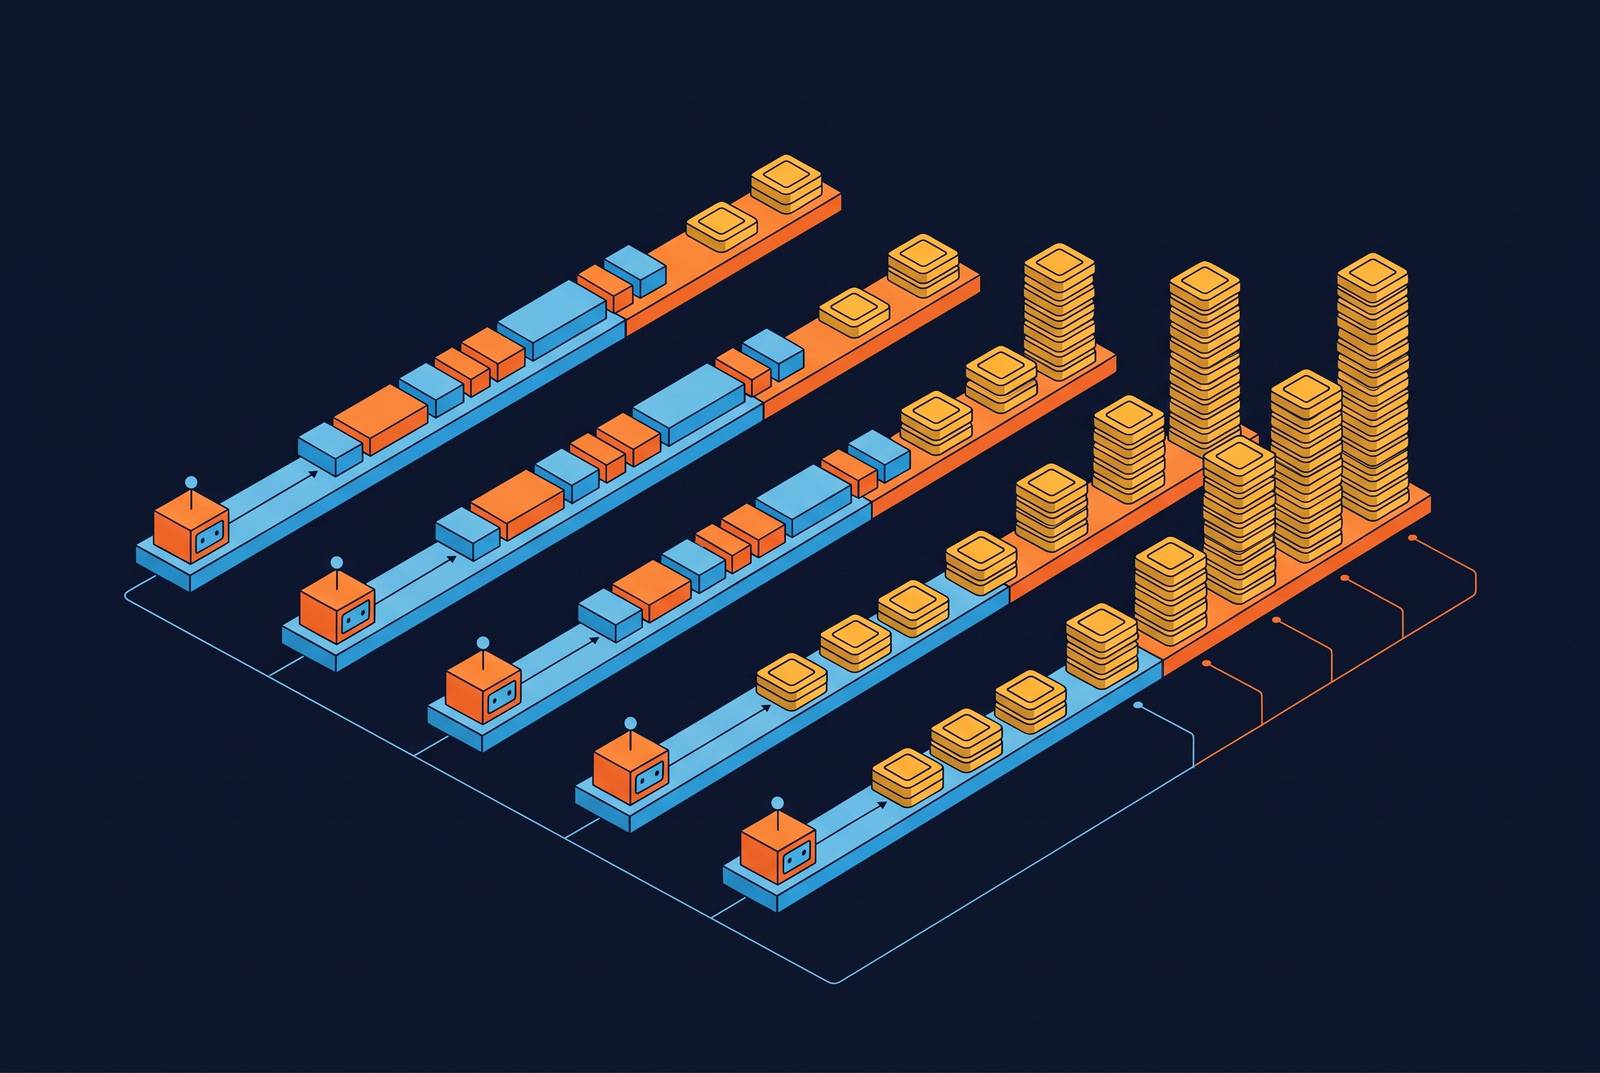
A coding task can begin with an architect defining the structure, move to an engineer implementing it, and pass through a reviewer and reviser. Each role gets the task context and outputs from earlier steps, then adds more material for the next step. Iteration adds further calls across those roles, sometimes in parallel. The handoff is therefore both a coordination step and a new processing cost. A single autonomous build session can make hundreds of sequential model calls.
Anthropic's API pricing shows that the computer-use toolset and browser toolset each add thousands of input tokens per request before any screenshot. Repository context and prior outputs then enlarge the material processed on successive turns. ProgRouter identifies repeated calls and long-horizon context as sources of high token consumption, compute usage, energy demand, and latency. When parallel branches converge, the synthesizer also receives their combined outputs.
These costs are additive in the accounting ledger, but the architecture multiplies the events that enter it. Liu and Li's framework keeps separate records of the resources each event uses, what it costs, and its risk. Summing those events reveals what a cheap-looking invocation conceals. It also explains why per-task and session-hour pricing models are becoming relevant beside per-token prices.
Why retries and recovery loops are a disproportionate share of the bill
Normal handoffs create expected overhead, but failures can force the pipeline to pay for the same context again. Glite ARF found that prompt-encoded rules retained a low-single-digit failure rate across thousands of agent invocations. Over a multi-week campaign, those lapses compounded into dozens of broken artifacts. A small probability per invocation was therefore a recurring operational cost.
A retry carries more than the tokens needed to express another attempt. Without effective reuse, it can resend, re-prefill, and rebill the full context accumulated before the failure. Liu and Li's framework identifies recovery-loop misalignment as a distinct form of cost–utility misalignment. Recovery from a genuine fault is useful, but repeated steps with no marginal utility consume budget without moving the task forward.
Glite ARF addresses this with deterministic verifier scripts that refuse to advance until an artifact conforms to a versioned specification. Rules live in code that fails loudly. Glite ARF's 2026 reporting puts the structural machinery at approximately 1% of wall-clock time. That provides a concrete basis for treating verification as part of the pipeline, rather than budgeting for repeated repair after failures spread.
How role specialization and model assignment change the cost curve across the team
Once the sources of spend are visible, model assignment becomes a more precise decision than choosing one model for every agent. AgentCARD evaluates role assignments and deployment modes together, combining role-decomposed evaluation with a unified API/self-hosted cost model. Its Pareto-frontier analysis identifies configurations where cost cannot be reduced without sacrificing accuracy. Its contribution-based diagnostic helps find the role that holds back performance. That makes a targeted upgrade possible without upgrading the whole team.
A planner that determines task structure may justify a frontier model, while an executor handling mechanical subtasks may not. The distinction depends on the task domain. AgentCARD examines which models to assign to each role, while ProgRouter addresses which model to use during execution. Together, they make model selection a question of where stronger reasoning changes the result.
Role-aware orchestration does add setup complexity. However, that configuration effort is a fixed investment whose savings can recur on each run. Mixing models and deployment modes changes the cost curve across the team instead of merely lowering the price of an unchanged workflow.
How online step-wise routing cuts cost without sacrificing output quality
Static assignments cannot capture every change in task difficulty. A routine step may uncover a harder problem, while a hard task may reach a point where all that remains is mechanical work. ProgRouter argues that model choice should reflect current progress, remaining difficulty, and cost-efficiency requirements. Its online, step-wise routing addresses what a one-shot, query-level decision cannot. The router reassesses the workflow as it develops.
ProgRouter first scores progress using both broad workflow outcomes and finer signals, including subtask completion, progress trends, and workflow state quality. A dual-path predictor and adaptive meta-gating then estimate how much progress each candidate model could add. In practical terms, the router balances expected progress against the remaining cost budget.
That balance matters because both extremes have a failure mode. Always choosing the strongest model can exhaust the budget early, while excessive conservatism can degrade quality by withholding stronger reasoning. ProgRouter's experiments on HumanEval Plus, MBPP, MATH-500, and ASQA show reduced operating cost relative to key baselines while maintaining strong task-solving performance. Those results span agentic code generation, mathematical reasoning, and retrieval-augmented QA, rather than establishing an unconditional guarantee for every workflow.
The prefill redundancy problem in parallel branches and one structural fix
Routing can reduce the cost of reasoning, but it does not remove redundant processing at branch merges. The standard approach concatenates worker outputs into an expanded text prompt for a downstream synthesizer. That discards the original DAG structure and re-encodes information already processed during worker decoding. The extra prefill comes from the communication interface.
Georgia Tech and Meta's Parallel-Synthesis framework proposes an emerging alternative in which the synthesizer directly consumes the workers' KV caches. A cache mapper calibrates independently generated branch caches, and a fine-tuned synthesizer adapter enables generation through that interface. The approach eliminates redundant prefill computation at the merge step. It is an architectural option with a specific implementation requirement.
Parallel-Synthesis matches or outperforms text-based synthesis on seven of nine downstream datasets and reduces time-to-first-token by 2.5×–11×. The datasets span math, science QA, code generation, GAIA, and multi-agent database diagnosis. Summarizing branches offers another mitigation, but summaries still need generation, serialization, and prefill, and may lose details needed downstream.
What prompt caching actually saves across a multi-turn, multi-agent session
Prompt caching addresses a more accessible form of repetition. When agents resend the same system prompt and repository context on every turn, supported APIs can charge cache reads at a fraction of the normal input-token price. Anthropic prices a Claude Opus cache read substantially below a full input read. For non-interactive work, Anthropic, OpenAI, and Google also discount batching by half. These controls change the price of repeated work without changing which role performs it.
Without caching, each agent can incur full input processing charges for shared context. When context can be reused from the cache, it costs less to send again, though calls and other token costs still have to be paid. Cache utilization therefore belongs in the cost model beside model choice and worker count.
aGiTrack makes that utilization auditable by wrapping coding agents and recording per-turn cache-read and cache-write token counts in git commit messages. This separates actual reuse from an assumption that caching must be working. It also gives teams a way to distinguish expensive new context from expensive repetition. Caching provides a mechanical saving while leaving how long an agent may run unconstrained.
Why ungoverned agent autonomy is the mechanism that turns compounding costs into runaway spend
Spending can run away when agents can launch parallel workers, retry as long as they like, and keep growing their context without a circuit breaker. Each amplifier then operates without a bound on the total trajectory. A lower token price merely makes each step cheaper while leaving the number of steps unconstrained.
Gartner's analysis links token overspending to governance failures, including ungoverned autonomy, bloated context windows, and missing structured feedback on usage. These failures connect architecture to organizational exposure. When an engineering culture focuses only on using more AI, teams can use more without deciding what it should cost to finish a task.
Consumption-based pricing makes that connection more immediate than seat-based pricing. The bill varies with execution, while limited transparency into token calculation and billing can weaken forecasts. Visibility after a run helps explain an overrun but cannot stop the run that caused it. Teams need limits enforced while the work runs, before more workers and retries add to the bill.
How do teams enforce AI coding agent budget caps before costs spiral
Effective enforcement is a layered control stack. Hard session limits cap how much work can run, worker-level attribution shows where the spending comes from, and team budgets with soft alerts show when spending drifts over time. Anomaly detection flags runaway loops, role-based model access limits routine use of frontier models, and approval thresholds gate long autonomous runs. Each tier addresses a different way that a workflow can exceed expectations. An alert warns that a limit is near, while a hard cap must stop the run when it reaches that limit.
Ellipsis enforces budget caps at agent invocation. Its repository-defined YAML agents run in isolated cloud sandboxes, with credentials minted per session and revoked with the sandbox at teardown. Every tool call, diff, and token is logged and attributable to a person or trigger. Session-level spend caps and audit trails thus sit in the execution architecture. This is distinct from prompt instructions asking an agent to conserve tokens.
Enforcement also needs enough detail to explain its decisions. With managed infrastructure such as Ellipsis, audit trails support attribution to the agent, workflow stage, and session rather than leaving teams to reconstruct spend from fragmented logs. The broader observability requirement includes model and version, task description, tool commands and exit codes, file writes, network activity, and credential use. Glite ARF's deterministic verifiers complement financial limits by blocking invalid progress before it causes more repair work. Hard-cap enforcement and graceful shutdown are separate things to check, and a claim that spending is capped does not by itself tell teams what happens to unfinished work.
Translating the compounding model into a team-level cost discipline
Useful planning considers what a completed trajectory costs, which events improve the result, and where additional spending stops producing value. Per-call metrics reveal local prices but miss the relationship between retries, handoffs, and completion.
Controls become more effective when they address the source of accumulation. Repeated context calls for reuse, misplaced model capacity calls for role-aware assignment or routing, and failed progress calls for deterministic verification. None of those efficiency measures replaces a financial boundary on autonomous execution. Conversely, a cap without attribution can stop spending without explaining why the task consumed its allowance.
Engineering leaders can therefore treat cost efficiency and budget enforcement as complementary disciplines. The first reduces the resources needed for useful completion, while the second bounds exposure when execution departs from that plan. Hard budget caps should be based on how the pipeline runs across sessions, workers, and time periods, with those facts taking the place of assumptions from a per-seat spreadsheet.
Sources
- ProgRouter: Online Progress-Guided Orchestration for Multi-Agent LLM Workflows under Quality-Cost Tradeoffs
- Towards Direct Latent-Space Synthesis for Parallel Branches in LLM-Agent Workflows
- Glite ARF: Verifier-Driven Research with Parallel LLM Coding Agents
- Cost-Utility Alignment in LLM Agent Trajectories:Profiling,Attribution,Diagnosis,Adaptation,and Evaluation
- Specialize Roles, Mix Deployments: Pushing the Cost-Accuracy Frontier of LLM Agent Teams